Technology School: Behind the Scenes of Crawling, Indexing, and Ranking
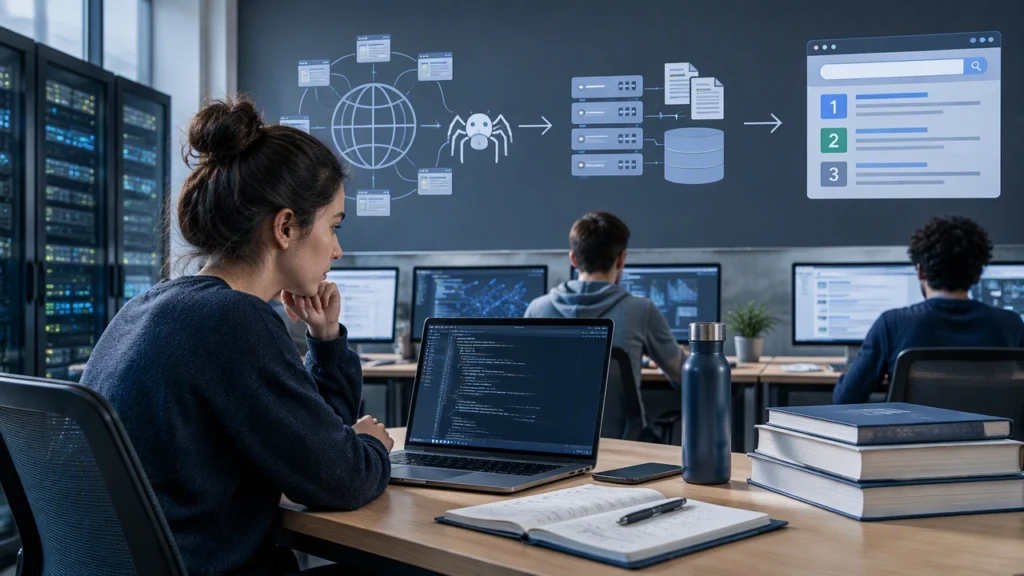
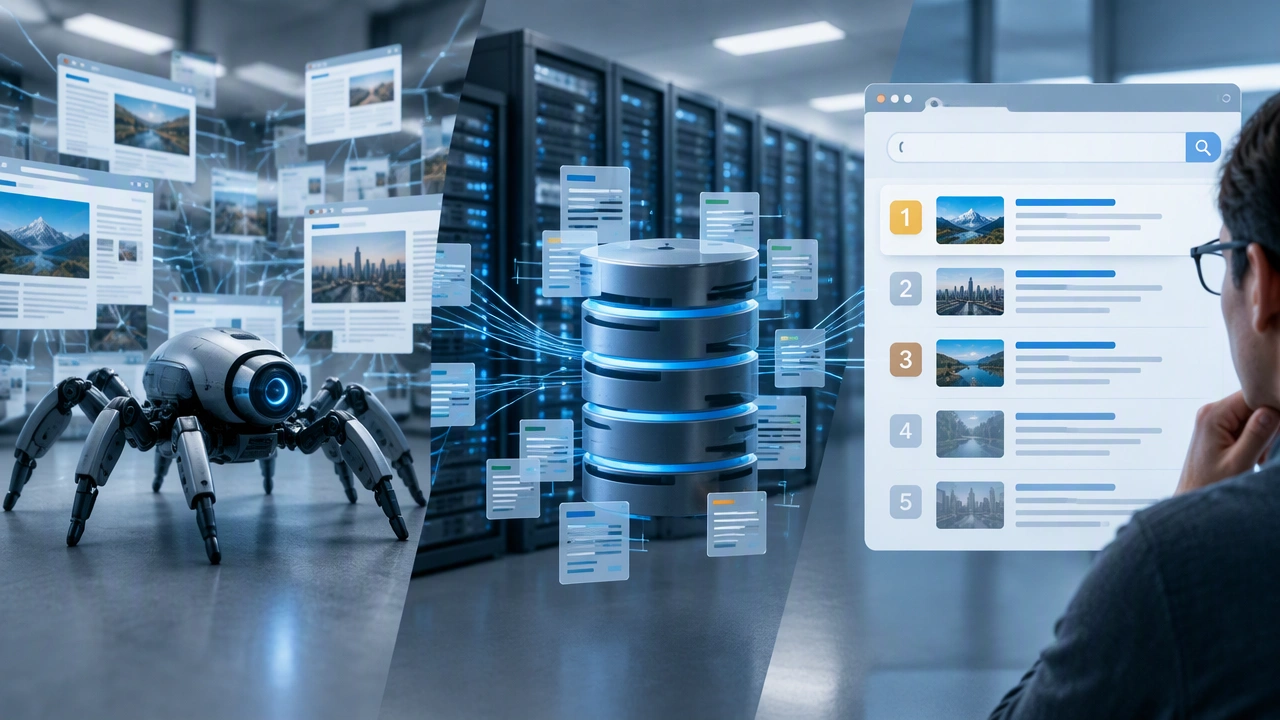
When you type a question into a search box, you usually expect the right answer within seconds. That speed hides a lot of careful engineering. If you have ever wondered how does a search engine find and rank answers, the short version is: it discovers the web, organizes what it finds, and then decides which pages deserve attention for each query. In this technology school style walkthrough, we will look behind the curtain at crawling, indexing, and ranking, and see how each step helps assemble the results page you see.
Crawling: discovering the web page by page
Crawling is the discovery phase. A search engine sends out automated programs, often called crawlers or spiders, that follow links from one page to another. The crawler reads a page, extracts the text, the images, the links, and the metadata, and then queues up the next pages to visit. This is how the system learns that new pages exist and that old pages have changed.
Not every page can or should be visited all the time. Crawlers use a priority system. Pages that change frequently, such as news articles or product listings, may be recrawled more often. Stable pages, like a long-lived terms-of-service document, might be revisited less often. Crawlers also respect rules set by site owners, including the robots.txt file and meta directives, which say which parts of a site may be accessed and how quickly. These rules help keep crawling polite and prevent overloading a single server.
Scale matters here. The web is enormous, so crawlers are designed to run in parallel, store their queues efficiently, and handle errors gracefully. If a server is slow or returns a temporary error, the crawler may back off and try again later. If a page is blocked or not useful, it may be skipped. The goal is not to download the entire web blindly, but to build a high-quality, up-to-date collection of pages that can be searched.
Indexing: turning pages into a searchable structure
Once a page is crawled, the next step is indexing. Raw HTML is not enough. The system parses the content, identifies the main text, removes boilerplate, and understands the language and structure. It builds an inverted index, which maps words and phrases to the pages that contain them. Think of it as a giant catalog that lets the engine quickly find all documents that mention a term, and even see how often and where that term appears.
Modern indexes store much more than simple keyword lists. They record signals like the title, headings, anchor text from links, page quality indicators, and whether the content is fresh. They may store information about entities, such as people, products, or places, and how they relate to one another. For images and videos, separate indexes may hold captions, alt text, visual features, and even transcripts. All of this extra structure helps the engine understand meaning, not just words.
Indexing also handles deduplication and canonicalization. Many pages are very similar or are copies of the same content. The engine tries to pick one canonical version and group near-duplicates together. This reduces clutter and avoids showing many nearly identical results. Pages that are too thin, unsafe, or spammy may be downranked or excluded from the index entirely.
Ranking: deciding which answers deserve the spotlight
Ranking is where the engine turns a query and an index into an ordered list of results. It starts by matching the query to candidate documents. Then it scores those documents using many signals. Classic signals include how well the words in the query match the page, how important the page seems based on links from other sites, and how fresh the content is. Newer systems also use semantic understanding, which tries to grasp the intent behind a query and the meaning of a page, even when the exact words do not match.
Consider a simple example. If you search for best running shoes for flat feet, the engine looks for pages that address running shoes, mention flat feet, and show signs of expertise and trust. It weighs factors like the depth of the content, the credibility of the source, user-friendly layout, and whether the page loads quickly on mobile. It also considers context such as your location, language, and device. A local store nearby might rank higher if the query seems local, while a detailed guide might rank higher for research intent.
Ranking is not static. Engines run experiments, measure outcomes, and adjust how signals are combined. They also use safety checks to reduce harmful, misleading, or low-quality results. All of this happens in milliseconds, across many candidate pages, to produce a short list that best matches the query.
Retrieval in the real world: how signals come together
To see how these steps combine, imagine you publish a clear guide about choosing running shoes. First, a crawler finds the page through a link on a popular running forum. Next, the indexer reads the text, extracts headings like cushioning, stability, and arch support, and notes that the page links to trusted shoe reviews. Later, when someone searches for shoes for flat feet, the ranking system retrieves your page as a candidate, checks its relevance, evaluates its authority, and compares it to other candidates. If the page is fast, mobile-friendly, and well-organized, these quality signals help it move up. If it is thin or outdated, it falls behind.
Why freshness and authority both matter
- Freshness helps for queries where the world changes quickly, such as product recalls, sports scores, or software releases.
- Authority helps for topics where expertise and trust are essential, such as health, finance, and safety.
- User experience helps for pages that are easy to read, fast to load, and free of intrusive distractions.
Search engines try to balance these signals based on the query. A medical question may lean toward authoritative sources, while a question about today’s news may lean toward fresh reporting.
What this means for readers and creators
For readers, this process explains why the top results often feel relevant and trustworthy. For creators, it suggests a practical path: be discoverable, be clear, and be useful. Make sure crawlers can reach your important pages. Write content that answers real questions with specific details. Organize your pages with descriptive titles and headings. Show expertise by citing sources you actually trust, adding original examples, and keeping information up to date. Improve speed and mobile experience, because those are part of quality.
It also helps to understand intent. Some queries need a quick fact, while others need a step-by-step guide. Matching your format to the intent, and updating your content as things change, can make a big difference over time.
The bottom line
Search results are not random, and they are not magic. They are the output of a careful pipeline that starts with crawling, moves through indexing, and ends with ranking. Each step adds structure, meaning, and judgment. By understanding that pipeline, you can better interpret the results you see and create content that earns its place in them. That is the essence of how a search engine finds and ranks answers: discover, organize, and decide, again and again, at massive scale.