What Is Machine Learning? A Plain-Language Guide Beyond the Hype
When headlines talk about machines that think, create, and even outsmart humans, it is easy to lose track of what the technology actually does. If you are looking for what is machine learning explained in simple terms, the answer is much more practical and less mysterious than science fiction suggests. Machine learning is not magic or artificial consciousness. It is a method for getting computers to improve at a task by finding patterns in data, rather than by following only explicit instructions written by a programmer.
What Machine Learning Actually Is (And What It Is Not)
Traditional programming works like a recipe: a developer writes step-by-step rules, and the computer follows them exactly. If you want to filter spam emails that way, you would have to write rules for every possible spam phrase, sender trick, and formatting quirk. That approach breaks quickly because language is too varied.
Machine learning flips the process. Instead of giving the computer all the rules, you give it many examples and a general goal. For spam filtering, you show it thousands of emails already labeled as spam or not spam. The system analyzes those examples, finds statistical patterns that distinguish the two groups, and builds a model that can make a prediction about new, unseen emails. The model is not memorizing; it is learning a general pattern that it can apply.
- What it is: Software that improves its performance on a specific task as it is exposed to more relevant data.
- What it is not: A computer that understands meaning, has common sense, or wants something. It has no intent or awareness.
- Key idea: The programmer defines the task, the data, and how success is measured. The algorithm figures out the internal adjustments to get there.
How Machine Learning Works in Simple Terms
You do not need math to understand the basic workflow. Most machine learning projects follow the same three stages, whether they are recommending movies or detecting fraudulent transactions.
1. Training Data Is the Textbook
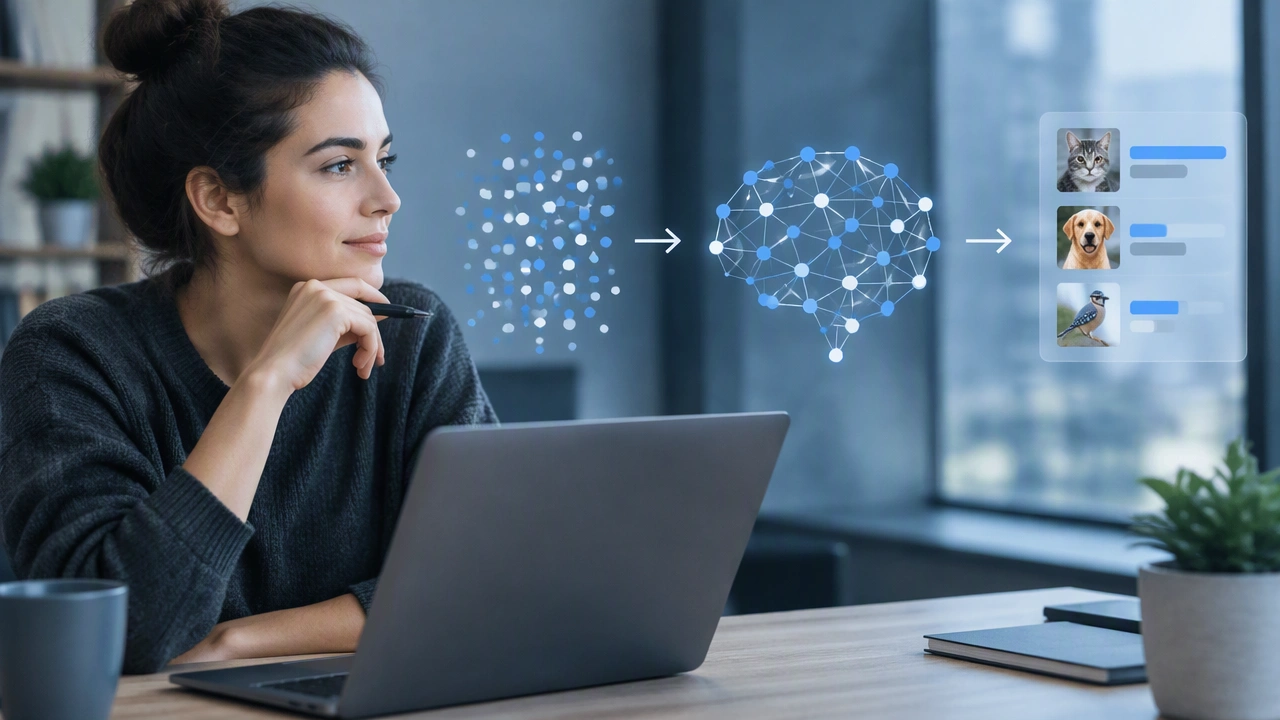
Everything starts with data. Data is the collection of examples the system learns from. For an image recognition model, this might be millions of photos labeled cat or dog. For a translation tool, it is pairs of sentences in two languages. The quality and diversity of this data matters more than almost anything else. If the textbook is incomplete or biased, the model will learn an incomplete or biased lesson, no matter how clever the algorithm is.
2. The Model Learns Patterns, Not Rules
A model is the mathematical structure that tries to map inputs to outputs. During training, the algorithm makes a guess, checks how far its guess was from the correct answer, and slightly adjusts its internal settings to do better next time. This cycle repeats millions of times. Think of it like tuning dials until the static clears. The model is not being told that pointed ears mean cat; it is gradually discovering which combinations of pixel patterns are most reliably associated with the label cat in the data it has seen.
3. Prediction and Feedback Loop
Once trained, the model is tested on new data it has never seen before. This is how we know if it actually learned a general pattern or just memorized the textbook. If it performs well, it can be deployed to make predictions on real-world inputs. In practice, good systems keep learning. When users mark a spam prediction as wrong, that feedback can become new training data to make the next version more accurate.
The Main Types of Machine Learning You Will Encounter
People group machine learning into a few broad types based on what kind of data and feedback they use.
Supervised Learning
This is the most common type. You train the model with labeled examples, where the correct answer is already known. The model learns to predict the label for new inputs. Examples include predicting a house price from its size and location, classifying an email as spam, or transcribing speech to text. It is supervised because a human has provided the correct answers during training.
Unsupervised Learning
Here the data has no labels. The goal is to find hidden structure on its own. For example, an e-commerce company might use unsupervised learning to group customers into segments based on purchasing behavior, without telling the system what those segments should be. It is useful for discovery, anomaly detection, and organizing large, messy datasets.
Reinforcement Learning
In this approach, an agent learns by trial and error in an environment, receiving rewards for good actions and penalties for bad ones. It is how systems learn to play games or how robots learn to navigate. The model is not shown the right answer; it has to experiment to discover a strategy that maximizes its reward over time.
Where You Already Use Machine Learning Every Day
Machine learning feels futuristic, but you probably interact with it many times a day without noticing. In most cases, it is working on a narrow, well-defined task:
- Search and recommendations: Search engines ranking results, streaming services suggesting what to watch next, and online stores recommending products based on your browsing history.
- Communication: Spam filters, autocorrect and predictive text, voice assistants converting speech to text, and automatic translation.
- Vision and navigation: Face unlock on phones, photo apps grouping pictures by person, and maps predicting traffic and estimating arrival times.
- Safety and finance: Banks flagging unusual transactions that might be fraud, and email providers detecting phishing attempts.
Notice the pattern: each system does one specific thing, and it does it by recognizing patterns in large amounts of historical data.
What Machine Learning Cannot Do: The Hype Check
Separating real capability from science-fiction hype is essential to understanding the technology. Here are the most common misconceptions.
- It does not truly understand. A chatbot can generate fluent sentences because it has learned statistical patterns in language, not because it understands meaning the way a person does. It can sound confident while being completely wrong.
- It is not objective by default. A model reflects the data it was trained on. If that data contains historical biases, measurement errors, or gaps, the model will reproduce and even amplify them.
- It cannot reason outside its training. A model trained to diagnose skin conditions from images cannot suddenly diagnose engine problems. It has no general common sense and struggles with situations that are very different from its training data.
- It needs a lot of data and human oversight. Machine learning does not create knowledge from nothing. It requires carefully collected data, clear evaluation, and ongoing human checks to stay accurate and safe.
Machine Learning vs. Artificial Intelligence vs. Deep Learning
These terms are often used interchangeably, but they are not the same. Artificial intelligence is the broadest term: any technique that lets computers perform tasks that would normally require human intelligence. Machine learning is a subset of artificial intelligence: a specific approach where systems learn from data. Deep learning is a subset of machine learning that uses multi-layered neural networks inspired by how neurons connect. Deep learning is especially good for complex data like images, audio, and natural language, which is why it powers many recent advances, but it also requires more data and computing power than simpler machine learning methods.
How to Start Understanding Machine Learning Without Coding
You do not need to become a programmer to build a realistic mental model of how it works. Focus on the concepts behind the tools.
- Think in terms of inputs and outputs. For any ML product, ask: What data goes in, what prediction comes out, and how is success measured?
- Ask about the data. Where did the training data come from, who labeled it, and what might be missing or overrepresented?
- Look for narrow tasks. Be skeptical of claims that a single system can do everything. Useful machine learning today is almost always narrow and task-specific.
- Test the limits. Try giving a system an unusual or edge-case input. How it fails tells you a lot about what it has actually learned.
Machine learning is a powerful tool for finding useful patterns at a scale no human could manage manually. It can automate routine decisions, surface insights in complex data, and make many everyday products more helpful. It does not, however, give computers beliefs, goals, or understanding. When you see a new claim about what AI can do, the most useful question is not whether the machine is intelligent, but whether it has been shown enough of the right kind of data to reliably perform that specific task.